About this episode
Seventy3:借助NotebookLM的能力进行论文解读,专注人工智能、大模型、机器人算法方向,让大家跟着AI一起进步。
今天的主题是:
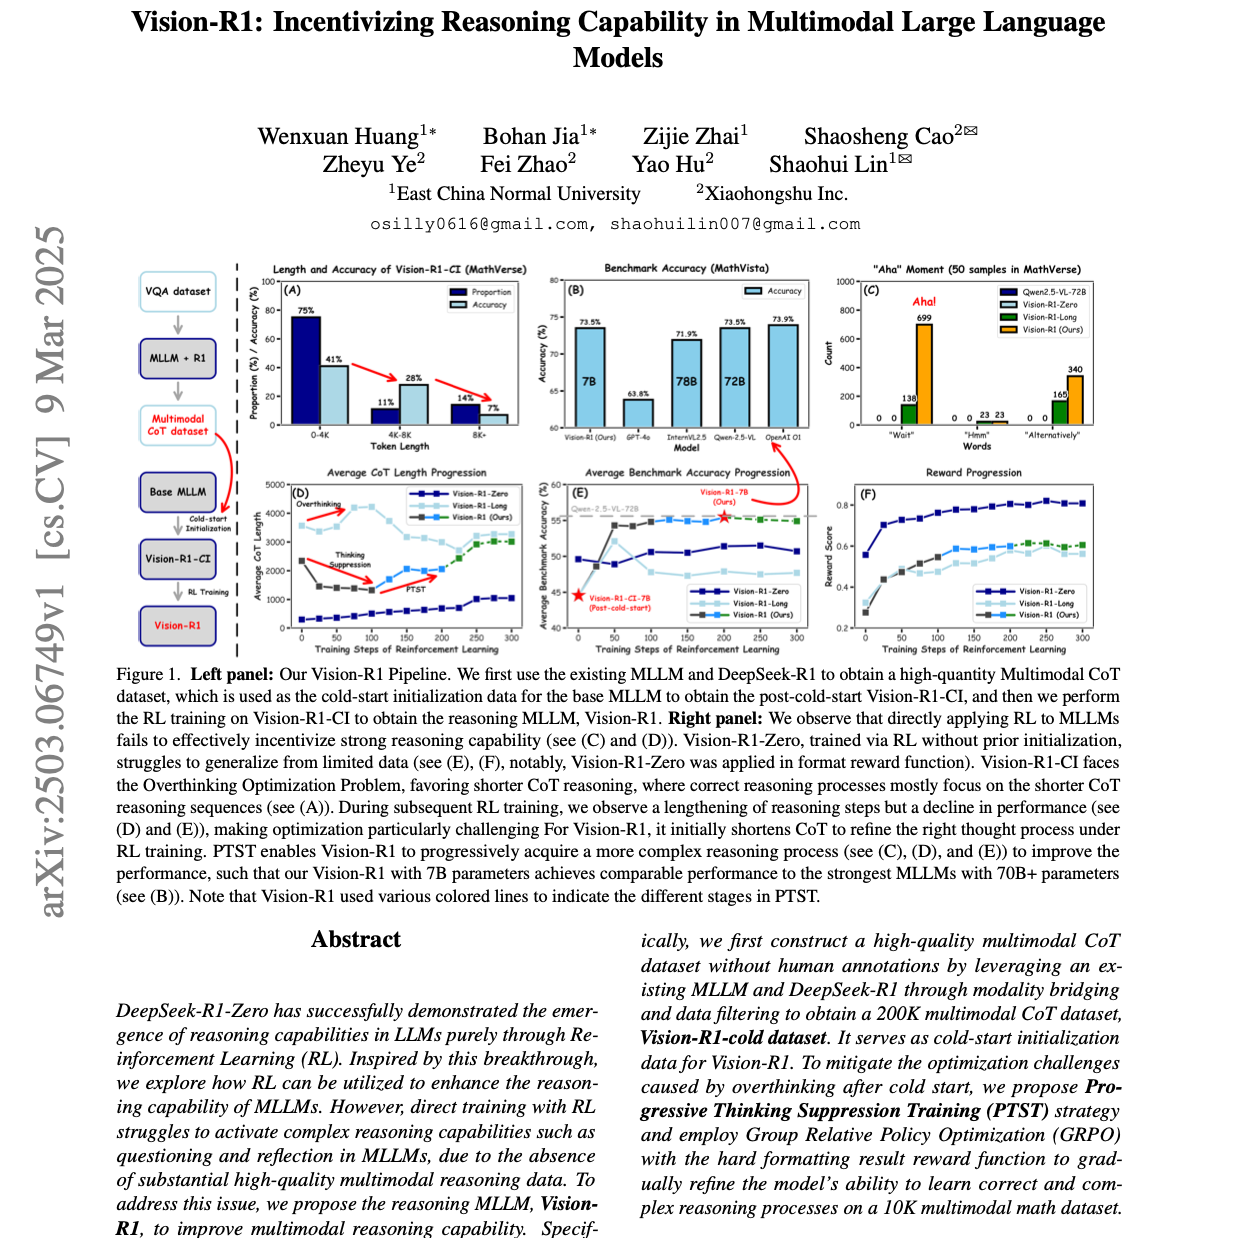
Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models
Summary
这篇研究探讨了如何通过强化学习(RL)增强多模态大型语言模型(MLLM)的推理能力,并提出了 Vision-R1 模型。研究首先构建了一个 高质量、无需人工标注 的多模态思维链数据集,用于对基础 MLLM 进行 冷启动初始化,从而初步学习类人推理模式。为了克服初始化后出现的“过度思考”优化难题,研究引入了 渐进式思维抑制训练(PTST) 策略,结合 GRPO 算法和硬格式化结果奖励函数,引导模型逐步完善推理过程并延长思考链,最终显著提升了 Vision-R1 在数学推理任务上的表现。尽管 Vision-R1-7B 参数量较小,但在多项基准测试中取得了与大型模型相当的性能。
原文链接:https://arxiv.org/abs/2503.06749
前往小宇宙评论区与主播互动
Get every episode summarized
Each time Seventy3 publishes, we email you a written briefing from the transcript — the topics, who appeared, and any specific claims, with the ad reads skipped.
Email me new episodesFree for 3 shows. No card needed.
Hosts & guests
No transcript yet
This episode has not been transcribed. Request it and it moves to the front of the queue.
More episodes
More from Seventy3
【第715期】Harness Handbook:AI智能体框架行为化表征指南
Seventy3
Sep 14, 202615:52skipped_language
【粉丝投稿001期】HydroGym:流体力学强化学习通用平台
Seventy3
Sep 14, 202620:11skipped_language

【第714期】ProxyMark:基于代理陷阱与流量水印的门罗币Tor节点去匿名化研究
Seventy3
Sep 13, 202623:12skipped_language
【第713期】LingBot-World-Infinity:无限交互式现实世界模拟器
Seventy3
Sep 12, 202624:54skipped_language