About this episode
Seventy3:借助NotebookLM的能力进行论文解读,专注人工智能、大模型、机器人算法方向,让大家跟着AI一起进步。
今天的主题是:
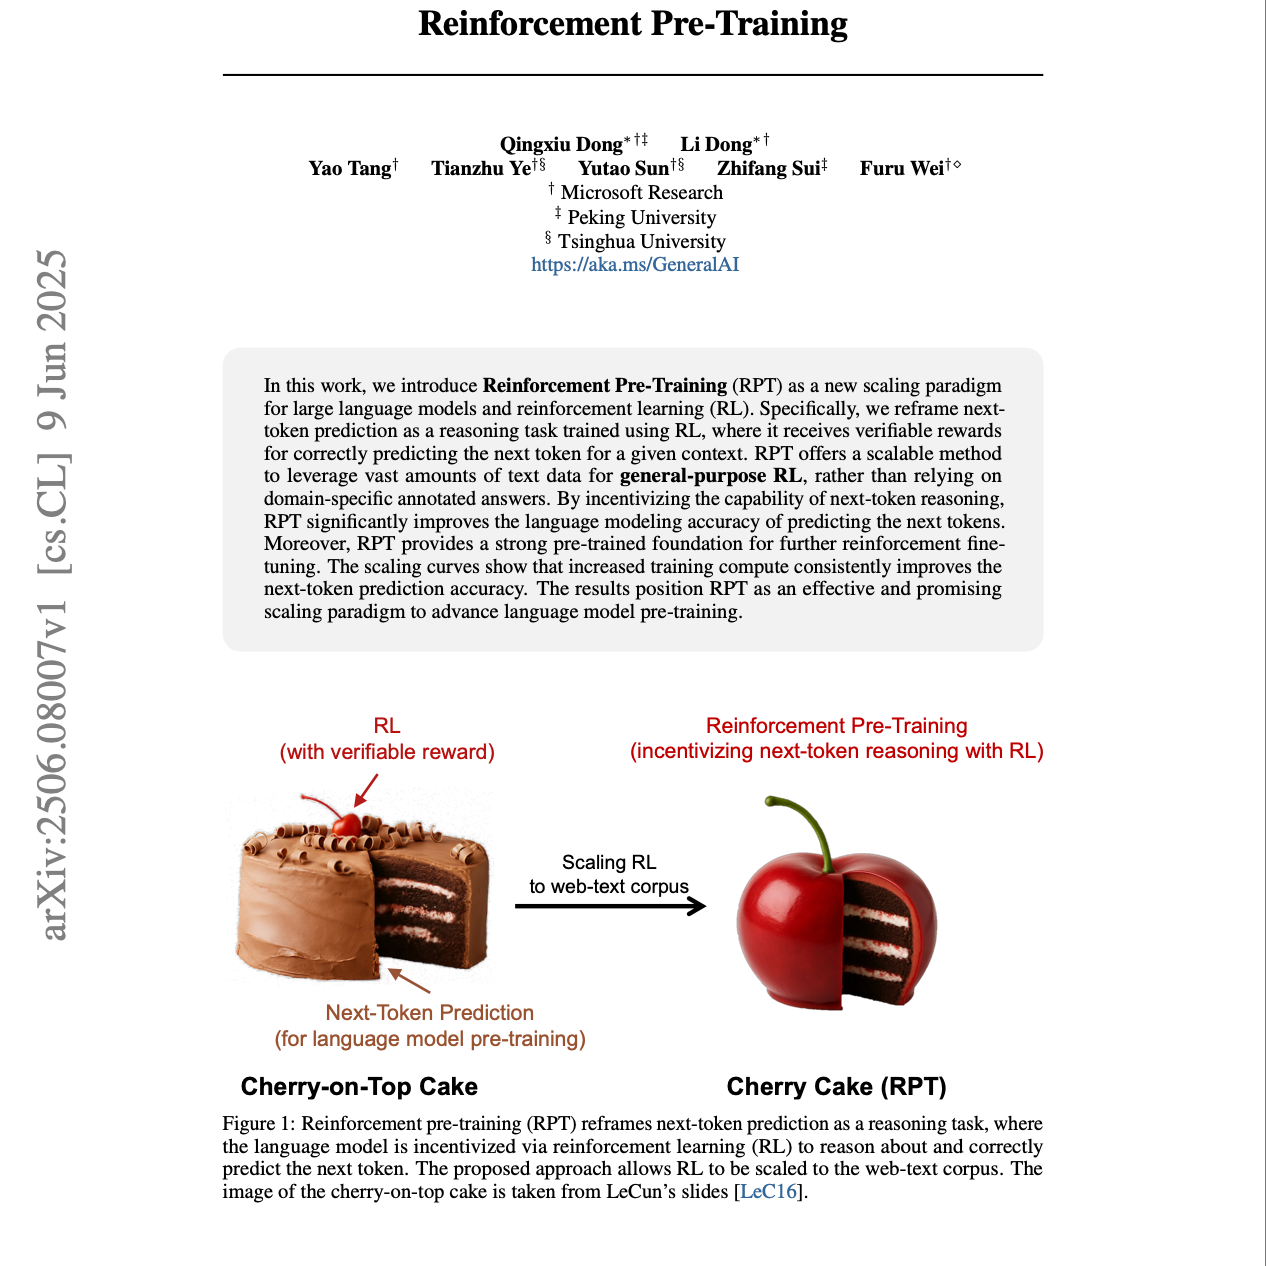
Reinforcement Pre-Training
Summary
该论文介绍了一种名为强化预训练(RPT)的新范式,旨在通过强化学习(RL)改进大型语言模型(LLMs)的预训练。RPT将传统的下一个词元预测任务重新定义为推理任务,模型因正确预测下一个词元而获得可验证的奖励。这种方法允许LLMs利用海量的文本数据进行通用的强化学习,无需依赖领域特定的标注。实验结果表明,RPT显著提高了下一个词元预测的准确性,并为后续的强化微调提供了更强大的基础,同时展示了随着训练计算量增加性能持续提升的良好扩展特性。该研究认为RPT提供了一个有前景的途径,能够通过根本性地重新思考预训练目标来开发更强大、更通用的LLMs。
原文链接:https://arxiv.org/abs/2506.08007
前往小宇宙评论区与主播互动
Get every episode summarized
Each time Seventy3 publishes, we email you a written briefing from the transcript — the topics, who appeared, and any specific claims, with the ad reads skipped.
Email me new episodesFree for 3 shows. No card needed.
No transcript yet
This episode has not been transcribed. Request it and it moves to the front of the queue.
More episodes
More from Seventy3
【第715期】Harness Handbook:AI智能体框架行为化表征指南
Seventy3
Sep 14, 202615:52skipped_language
【粉丝投稿001期】HydroGym:流体力学强化学习通用平台
Seventy3
Sep 14, 202620:11skipped_language

【第714期】ProxyMark:基于代理陷阱与流量水印的门罗币Tor节点去匿名化研究
Seventy3
Sep 13, 202623:12skipped_language
【第713期】LingBot-World-Infinity:无限交互式现实世界模拟器
Seventy3
Sep 12, 202624:54skipped_language