About this episode
Seventy3: 用NotebookLM将论文生成播客,让大家跟着AI一起进步。
今天的主题是:
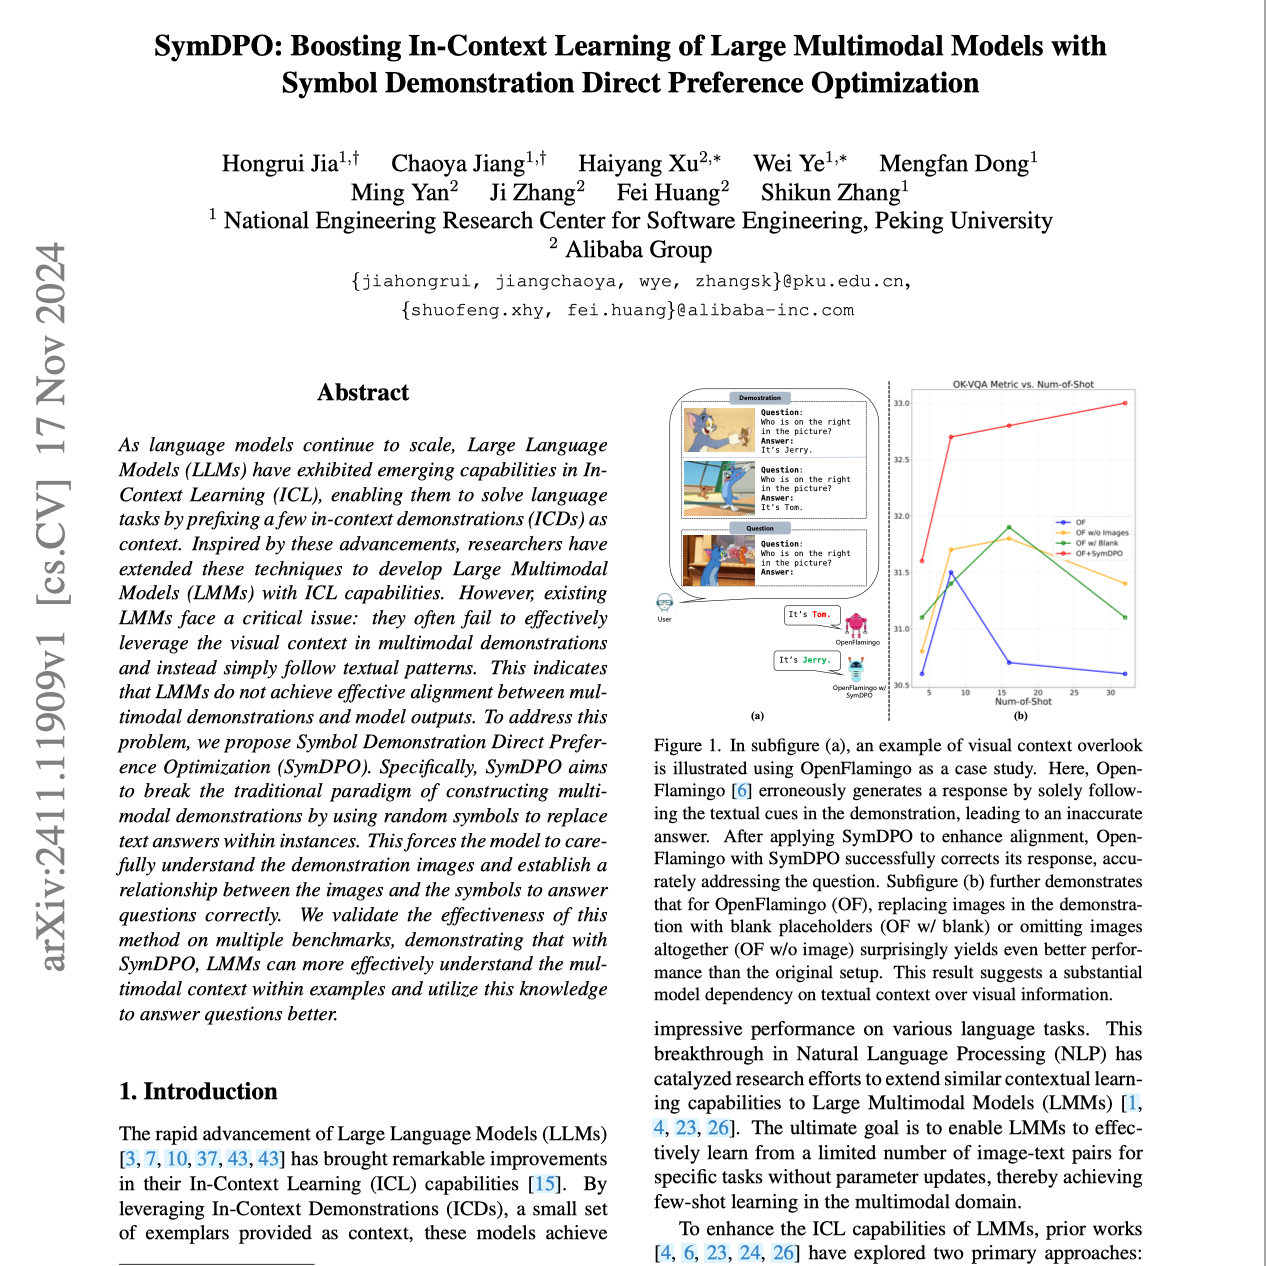
SymDPO: Boosting In-Context Learning of Large Multimodal Models with Symbol Demonstration Direct Preference Optimization
Summary
This research introduces SymDPO, a novel method to improve the in-context learning capabilities of Large Multimodal Models (LMMs). Current LMMs often prioritize textual information over visual context in demonstrations, leading to inaccurate results. SymDPO addresses this "visual context overlook" by replacing text answers with symbols, forcing the model to rely on both visual and symbolic cues for correct responses. Experiments across various benchmarks demonstrate that SymDPO significantly enhances LMM performance compared to existing methods like General DPO, Video DPO, and MIA-DPO. The improved performance highlights SymDPO's success in fostering a more balanced understanding of multimodal information within in-context learning scenarios.
原文链接:https://arxiv.org/abs/2411.11909
前往小宇宙评论区与主播互动
Get every episode summarized
Each time Seventy3 publishes, we email you a written briefing from the transcript — the topics, who appeared, and any specific claims, with the ad reads skipped.
Email me new episodesFree for 3 shows. No card needed.
Hosts & guests
No transcript yet
This episode has not been transcribed. Request it and it moves to the front of the queue.
More episodes
More from Seventy3
【第715期】Harness Handbook:AI智能体框架行为化表征指南
Seventy3
【粉丝投稿001期】HydroGym:流体力学强化学习通用平台
Seventy3

【第714期】ProxyMark:基于代理陷阱与流量水印的门罗币Tor节点去匿名化研究
Seventy3
【第713期】LingBot-World-Infinity:无限交互式现实世界模拟器
Seventy3