About this episode
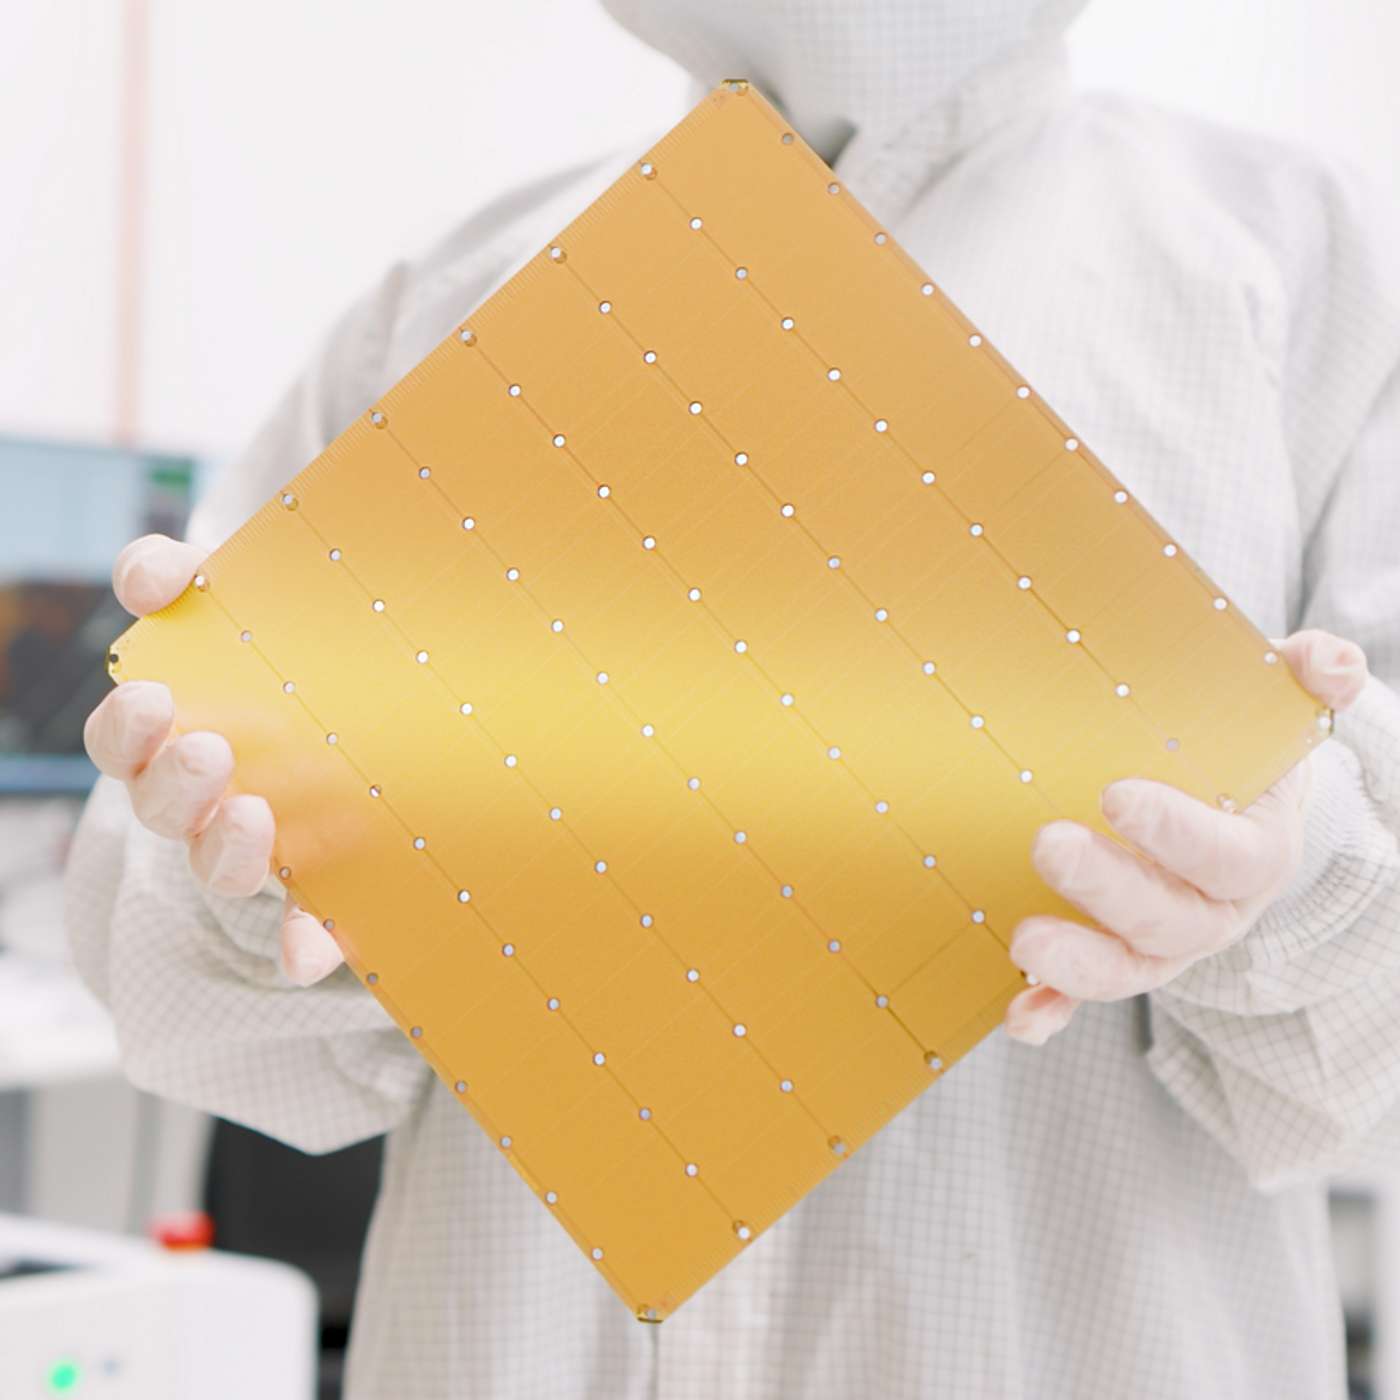
In this episode, we discuss Cerebras Systems and their Wafer-Scale Engine, currently the fastest LLM inference processor, with 7000x more memory bandwidth than nVidia H100. Together with G42, they’re also developing the Condor Galaxy, potentially the largest AI supercomputer. Is this all just hype? What are the real world use cases and why should average users care about it?
Get every episode summarized
Each time DecodeFM publishes, we email you a written briefing from the transcript — the topics, who appeared, and any specific claims, with the ad reads skipped.
Email me new episodesFree for 3 shows. No card needed.
Hosts & guests
No transcript yet
This episode has not been transcribed. Request it and it moves to the front of the queue.
More episodes


